Auditor Benchmark
How the auditing benchmark works. We will provide participating auditors with API access to all assistants in the benchmark, together with each assistant's stated specification. Each auditor will receive the same total budget of API calls and must decide how to use it to interact with the assistants and determine which are following their specifications (on-spec) and which are not (off-spec). Auditors will return a label for each assistant, and we will evaluate their performance against the benchmark's hidden ground-truth labels. See the diagram below for a visual overview of the process.
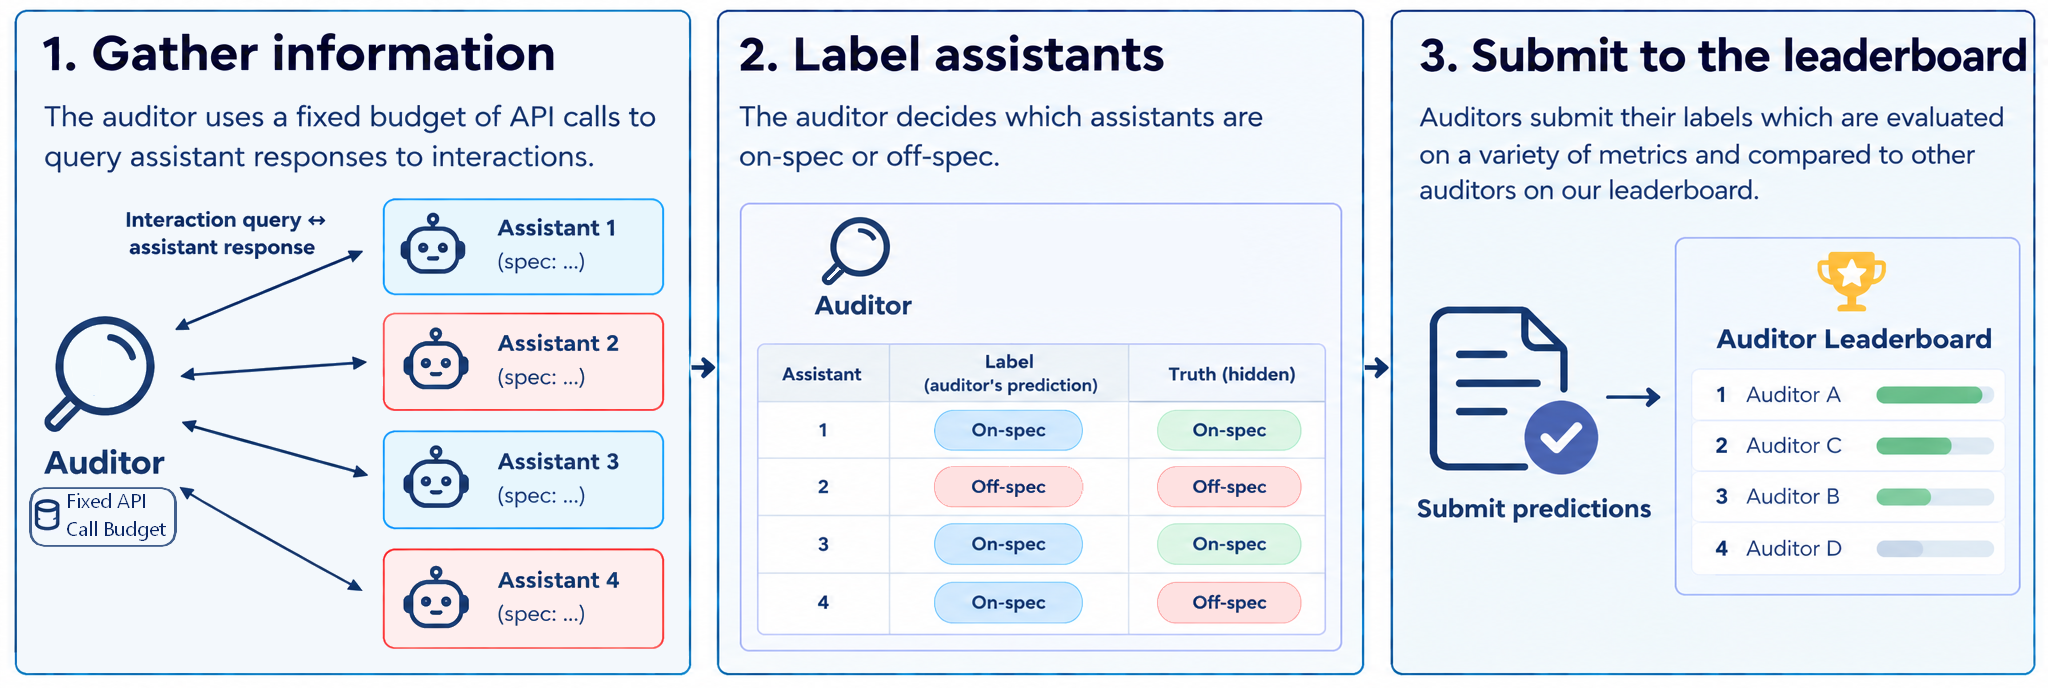
We report a variety of metrics that aim to give a holistic view of auditor performance. Some of these metrics aim to reward having a high rate of success in flagging off-spec public assistants, not flagging on-spec public assistants, or consistently flagging public assistants that are more able to shift the conversation towards hidden objectives. For a full ranked list of evaluated auditors, metrics and their explanation, check our Auditor Leaderboard.
To submit an auditor for evaluation, please enter in contact with our team at outreach-traust-moonshot@cornell.edu.
An interface for submission will be available in the future.